

For Vambo AI, getting the computing power to build a large African-language AI model was not the biggest challenge.
Finding enough African-language data was.
The Johannesburg-based company had access to a supercomputer through a United Nations Development Programme (UNDP)-backed initiative. It had the graphics processing units (GPUs) required to train a 1.5-billion-parameter model called MORENA across 12 African languages.
What it did not have was enough real text in those languages.
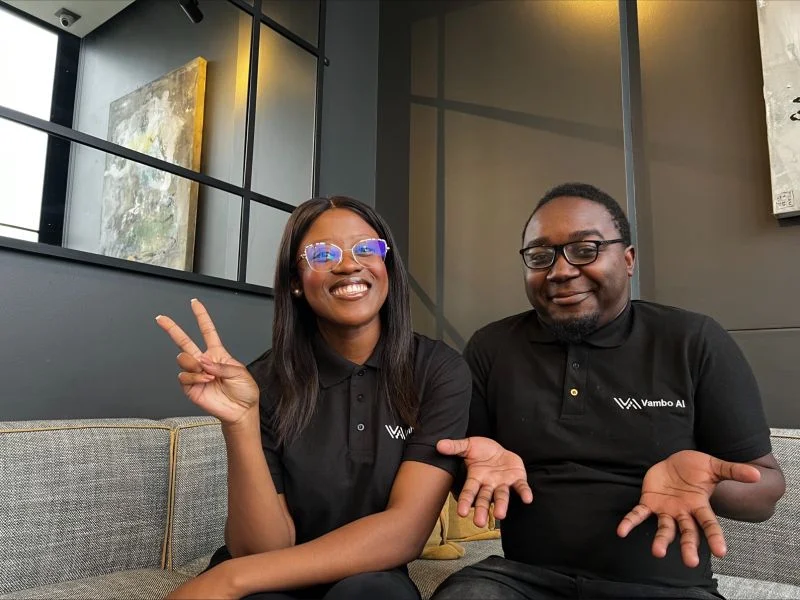
“Finding that much real data was close to impossible, so a lot of it was synthetic,” said Isheanesu Misi, Vambo’s co-founder and chief technology officer.
That shortage exposes a problem that could become a major constraint for Africa’s AI industry. The continent is home to thousands of languages and hundreds of millions of speakers, but many of those languages have little digital content available for training AI systems.
For developers, the problem is straightforward: an AI model cannot properly learn a language if there is not enough good-quality material for it to learn from.
And while companies can rent or access more computing power, creating years’ worth of reliable language data is considerably harder.
A model built around African languages
Vambo built MORENA specifically with African languages in mind rather than taking an existing general-purpose model and adapting it.
The model was trained on 251.7 billion tokens, of which 65.6 billion came from African-language data, according to its documentation.
Its language coverage includes Hausa, Yorùbá, Igbo, Nigerian Pidgin, Kiswahili, ChiShona, isiZulu, isiXhosa, Kinyarwanda, Setswana, Afrikaans and isiNdebele. It also works with English, French and code.
Vambo’s decision to build from scratch was partly driven by the limitations it saw in existing models. General-purpose AI systems are typically trained on much larger amounts of data from widely represented languages, which can leave them less capable when dealing with African languages.
The company says MORENA’s results show what is possible when those languages are given greater attention during training.
In tests covering the 12 African languages, MORENA recorded 1.408 bits per byte, which Vambo says was the lowest result among the 26 models it tested. The comparison included Lugha-Llama-8B, an 8-billion-parameter model, along with larger general-purpose systems.
MORENA also appeared to be more efficient at processing African-language text.
Its tokenizer the part of an AI system that breaks text into smaller units before processing used 1.39 times fewer tokens than Gemma 3 and 1.53 times fewer than Llama 3.2, according to Vambo’s model card.
When the internet doesn’t have enough of your language
The performance gains, however, do not remove the underlying data problem.
With so little usable text available for some African languages, Vambo had to generate synthetic material to supplement the real data.
That helped expand the training pool, but it also introduced new problems.
“You would find that some of the grammar of the outputs is close but imperfect,” Misi said.
Synthetic data served another purpose too. Vambo used it to help train MORENA for particular capabilities, including tool calling.
But synthetic data cannot completely replace the richness of real-world language.
A language is more than its dictionary and grammar. The way people actually speak, write, shorten words, switch between languages and use expressions in different contexts is difficult to reproduce perfectly with generated text.
That becomes even more important for languages that have millions of speakers but very little digital material.
Misi highlighted isiNdebele and Nigerian Pidgin as examples of languages where AI developers have very few resources to work with.
The consequence is that local developers can have ideas for useful AI applications without having the underlying language resources needed to build them.
“That means that the AI applications are extremely important and necessary, but they can’t be fully built by local innovators because they don’t have everything they need,” Misi said.
The other expensive piece: computing
Vambo still had to solve the computing problem, but this time it had help.
CINECA, an Italian inter-university consortium focused on high-performance computing and research, provided access to its Leonardo supercomputer through the UNDP AI Hub for Sustainable Development.
That support meant Vambo did not have to pay for the GPUs used to train MORENA.
Some training runs used 512 GPUs at the same time.
For a company trying to build a large AI model, that kind of access can make the difference between an ambitious research project and one that never gets off the ground.
“Without access to that kind of compute power, this project would have been dead on arrival,” Misi said.
But Vambo’s experience points to a bigger issue for Africa’s AI ecosystem.
The continent does not only need more GPUs or bigger data centres. It needs more of its languages represented in the digital datasets that AI systems depend on.
Without that foundation, African companies may have the engineers, ideas and computing infrastructure to build AI products, while still struggling to make those products work naturally for the people and languages they are meant to serve.
Training MORENA required significant computing power, but Vambo did not have to absorb the full cost.
The project used about 22,000 A100 GPU-hours, which would typically cost an estimated $25,000 to $40,000. Vambo’s direct cost, however, was zero because the computing resources were provided by CINECA through the UNDP AI Hub for Sustainable Development.
For Misi, the project shows what African AI teams can achieve when they are given access to infrastructure that would otherwise be out of reach.
But it also raises a practical question: what happens when that support is no longer available?
Access to subsidised computing can make it possible for startups and researchers to train large models, but building a sustainable AI industry requires access to that infrastructure beyond a single project.
MORENA is built to be used by others
Vambo is not presenting MORENA as a finished AI product for everyday consumers. Instead, the company sees it as a foundation that other developers can build on.
The model’s weights are available under an Apache 2.0 licence, allowing developers to use and adapt them. Vambo has also released smaller versions, including models with 500 million and 200 million parameters, for environments where computing resources are more limited.
The idea is to give developers a starting point instead of forcing each company to build its own foundation model from scratch.
A fintech company, for example, could take MORENA and fine-tune it for a specific financial service. An education company could adapt it for learning tools in a particular African language.
That could dramatically reduce the cost and time involved.
“If everyone is to try and build a model from scratch, it’s prohibitively expensive, complicated, time-consuming,” Misi said. “But fine-tuning could cost a hundred dollars or even less at times.”
The training data used to build MORENA, however, has not been released.
Africa’s AI race is also a language race
MORENA is part of a growing effort to make AI work better across Africa’s linguistic diversity.
The continent is home to more than 2,000 languages, but many of them have very little digitised text or speech available for training AI systems. That leaves developers with a difficult choice: build with limited real-world data, generate synthetic data, or spend significant resources collecting and preparing new datasets.
Several projects are already tackling the problem from different directions.
In Nigeria, N-ATLAS is being developed as a multilingual AI model focused on local languages. Google’s WAXAL project has also created an open-source speech dataset covering 21 sub-Saharan African languages.
These projects are addressing a problem that goes beyond language models themselves. If African languages remain poorly represented in digital datasets, many of the AI products built for the continent will continue to depend heavily on languages developed elsewhere.
GPUs are only half the equation
Computing infrastructure is gradually becoming more accessible through partnerships, research programmes and new investment.
Nigeria, for example, is developing more domestic AI computing capacity, while companies such as UduTech are building GPU infrastructure for African users. Semiconductor companies such as Chipmango are also working on chip development and training engineers in the field.
More recently, UduTech partnered with South Korean AI infrastructure company BARO AI to expand access to high-performance GPUs for governments, businesses and research institutions across Africa.
But more GPUs alone will not solve the continent’s AI problem.
For African-language AI to scale, developers need the entire pipeline: computing power, high-quality datasets, researchers who understand local languages, tools for cleaning and documenting those datasets, and reliable access to the data itself.
That may ultimately be the harder part of Africa’s AI race.
The continent can find ways to access more GPUs. Building the language data needed to teach those machines about Africa will take considerably longer.